Sampling-Based Constrained Policy Optimization
Sep 1, 2025
·
1 min read
Principal Researcher (Sep 2025 — Dec 2025)
- Proposed a sampling-based weight-space projection framework for enforcing safety constraints during policy updates, enabling scalable safe learning for large neural policies.
- Formulated policy optimization as a convex projection in parameter space, with theoretical guarantees that projected updates preserve objective improvement.
- Derived a sufficient stability condition linking weight updates to closed-loop constraint satisfaction, and embedded it directly into the optimization pipeline.
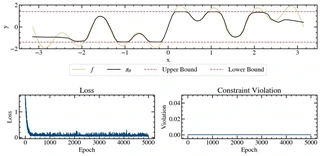
- Empirically demonstrated complete rejection of harmful supervision and safe performance gains in regression and imitation learning under adversarial experts.
Tech: PyTorch, Convex Optimization, Reinforcement Learning, Safe Learning.

Authors
Shengfan Cao
(he/him)
PhD Researcher in Autonomous Driving & Robotics
UC Berkeley Ph.D. candidate developing safe, machine-learning-based prediction, planning, and control systems for autonomous vehicles. First-author IEEE IROS oral presenter with 4+ years across machine learning, planning, and controls, spanning PyTorch research, CARLA evaluation, embedded-robot deployment, and C++ production planner integration.